Getting Started with Console OCR Processor
14 Aug 20267 minutes to read
The .NET OCR library is used to extract text from scanned PDFs and images in console applications with the help of Google’s Tesseract Optical Character Recognition engine.
Prerequisites
Version Compatibility
- Syncfusion.PDF.OCR.Net.Core supports .NET 8.0 and later versions.
Supported Inputs
The OCR processor supports the following input formats:
- Single-page and multi-page PDF documents
- Scanned images in common formats (JPEG, PNG, TIFF)
- Recommended DPI: 200 DPI or higher for optimal OCR accuracy
Required Software
- .NET 8 SDK or later
- Visual Studio, Visual Studio Code, or JetBrains Rider
Register the License Key
Starting with v16.2.0.x, if you reference Syncfusion® assemblies from trial setup or from the NuGet feed, you must add the Syncfusion.Licensing assembly reference and register a license key in your application. For more information, see the licensing documentation.
Include the following code in the Program.cs file to register the license key:
using Syncfusion.Licensing;

// Register Syncfusion license at application startup
SyncfusionLicenseProvider.RegisterLicense("YOUR LICENSE KEY");
- Beginning from version 21.1.x, the TesseractBinaries and Tesseract language data folders are now included by default; you no longer have to set these paths explicitly.
- The current NuGet package includes Tesseract 5.0, which provides support for 100+ languages.
Steps to perform OCR on an entire PDF document in Console application
Step 1: Create a new .NET console application project targeting .NET 8.0.
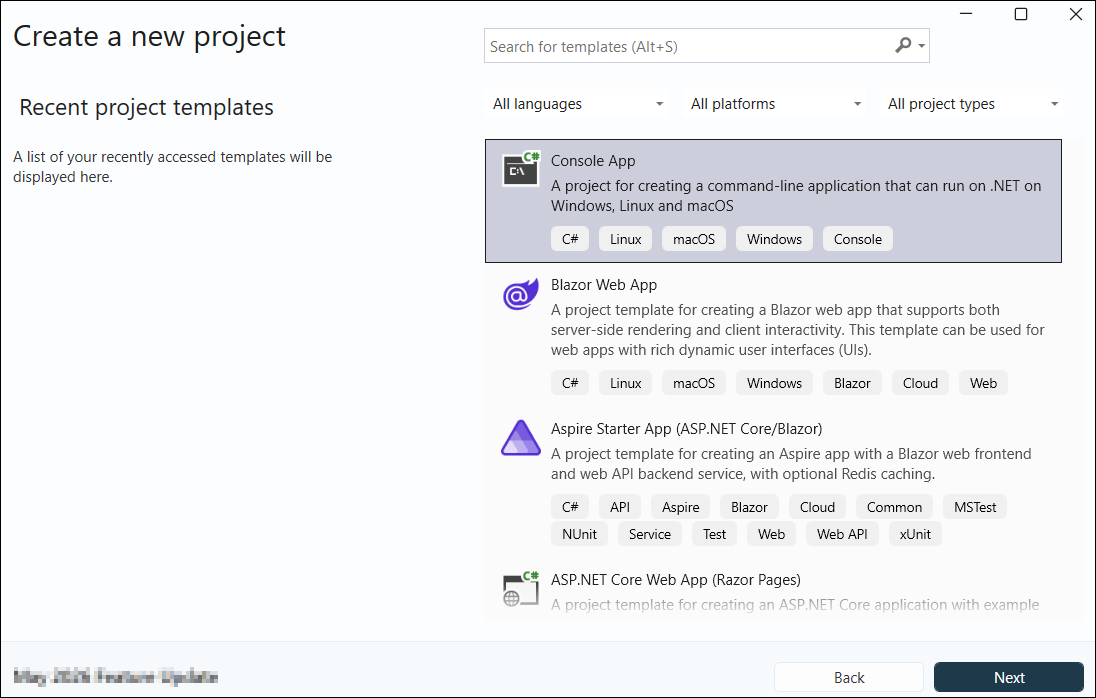
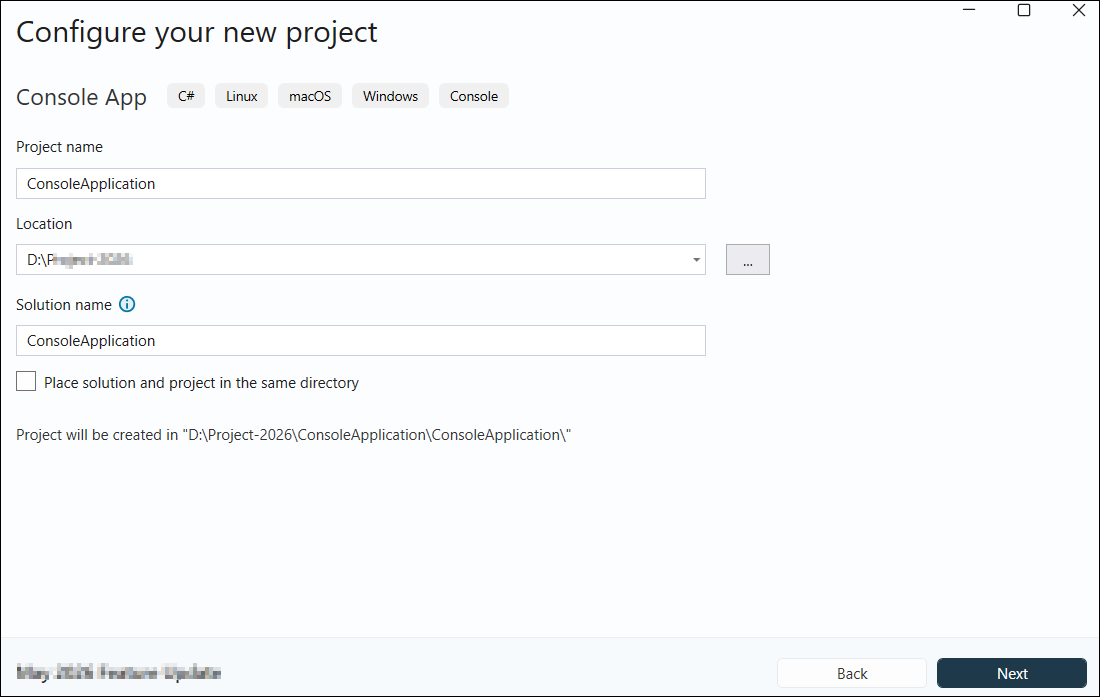
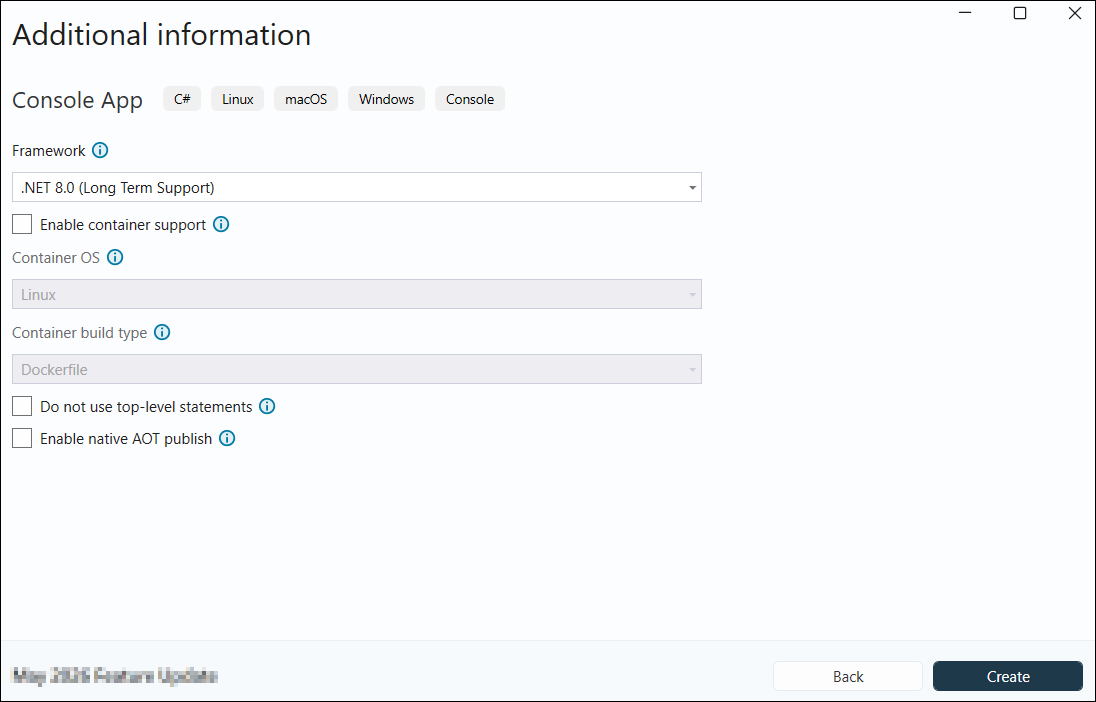
Step 2: In the project configuration window, name your project and select Next, then select the target framework (.NET 6 or later) and click Create.
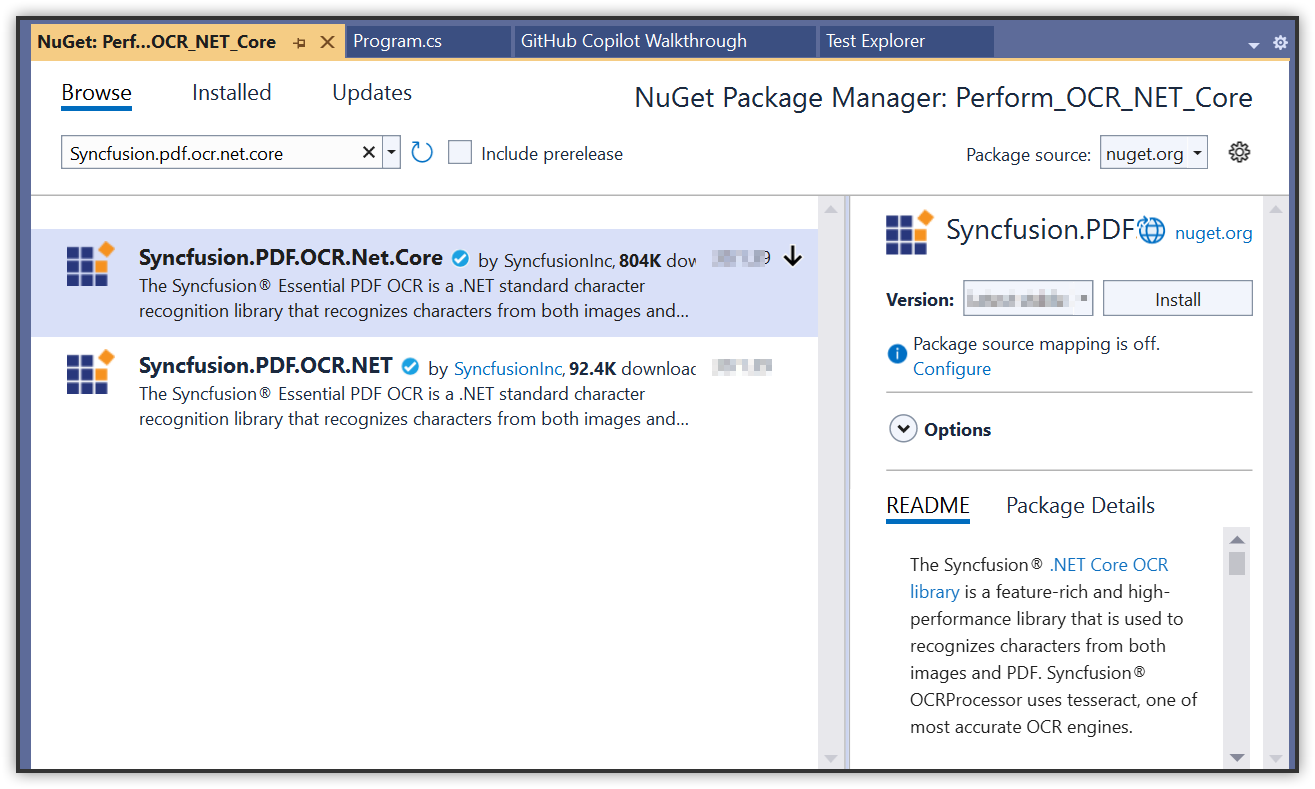
Step 3: Install the Syncfusion.PDF.OCR.Net.Core NuGet package into your console application from NuGet.org.
- Beginning from version 21.1.x, the TesseractBinaries and Tesseract language data folders are now included by default; you no longer have to set these paths explicitly.
- The current NuGet package includes Tesseract 5.0, which provides support for 100+ languages.
Step 4: Include the following namespaces in Program.cs:
using Syncfusion.OCRProcessor;
using Syncfusion.Pdf.Parsing;
Step 5: Include the following code sample in Program.cs using the PerformOCR method of the OCRProcessor class:
// Initialize the OCR processor
using (OCRProcessor processor = new OCRProcessor())
{
    // Load an existing PDF document
    PdfLoadedDocument document = new PdfLoadedDocument(Path.GetFullPath(@"Data/Input.pdf"));
    // Set the Tesseract version
    processor.Settings.TesseractVersion = TesseractVersion.Version5_0;
    // Set OCR language
    processor.Settings.Language = Languages.English;
    // Perform OCR on the document
    processor.PerformOCR(document);
    // Save the processed PDF to disk
    document.Save(Path.GetFullPath(@"Output/Output.pdf"));
    // Close the document
    document.Close(true);
}
Step 6: Build the project.
Click the Build button in the toolbar or press Ctrl+Shift+B to build the project.
Step 7: Run the project.
Click the Run button (green arrow) in the toolbar or press F5 to run the application.
Step 1: Open the terminal (Ctrl+`) and run the following command to create a new console application project targeting .NET 8 or later:
dotnet new console -n ConsoleApplication --framework net8.0
Step 2: Replace ConsoleApplication with your desired project name.
Step 3: Navigate to the project directory:
cd ConsoleApplication
Step 4: Use the following command in the terminal to add the Syncfusion.PDF.OCR.Net.Core package:
dotnet add package Syncfusion.PDF.OCR.Net.Core
Step 5: Include the following namespaces in Program.cs:
using Syncfusion.OCRProcessor;
using Syncfusion.Pdf.Parsing;
Step 6: Include the following code sample in Program.cs using the PerformOCR method of the OCRProcessor class:
// Initialize the OCR processor
using (OCRProcessor processor = new OCRProcessor())
{
    // Load an existing PDF document
    PdfLoadedDocument document = new PdfLoadedDocument(Path.GetFullPath(@"Data/Input.pdf"));
    // Set the Tesseract version
    processor.Settings.TesseractVersion = TesseractVersion.Version5_0;
    // Set OCR language
    processor.Settings.Language = Languages.English;
    // Perform OCR on the document
    processor.PerformOCR(document);
    // Save the processed PDF to disk
    document.Save(Path.GetFullPath(@"Output/Output.pdf"));
    // Close the document
    document.Close(true);
}
Step 7: Build the project.
Run the following command in terminal to build the project:
dotnet build
Step 8: Run the project.
Run the following command in terminal to run the application:
dotnet run
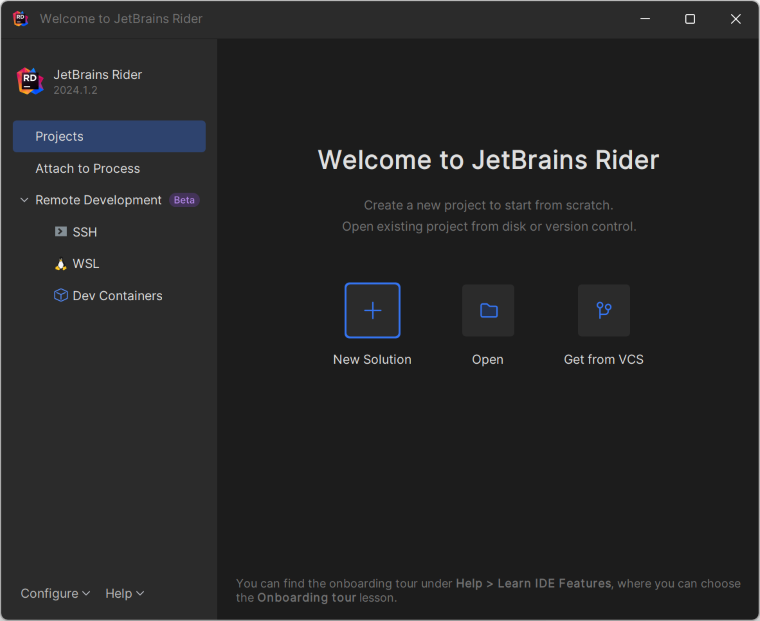
Step 1: Open JetBrains Rider and create a new .NET console application project:
- Launch JetBrains Rider
- Click New Solution on the welcome screen
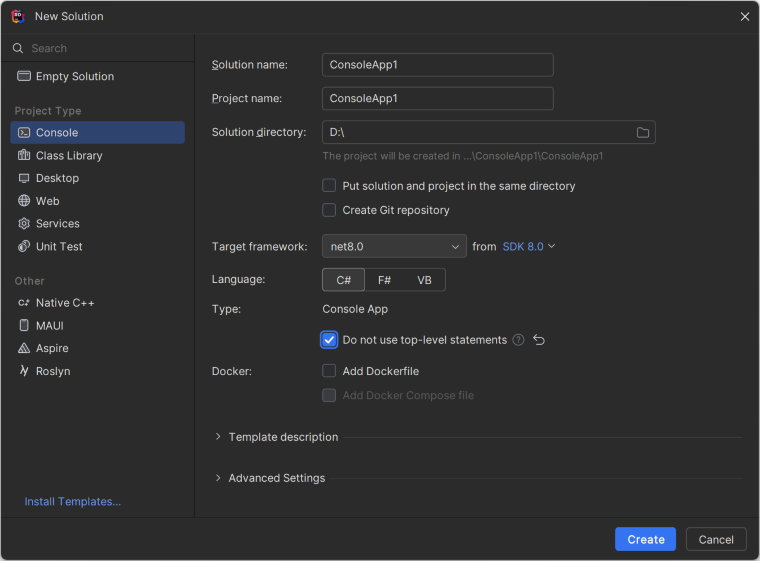
- In the new Solution dialog, select Console as the Project Type
- Enter a project name and specify the location
- Select the target framework(e.g., .NET 8.0, .NET 9.0 and .NET 10).
- Click Create
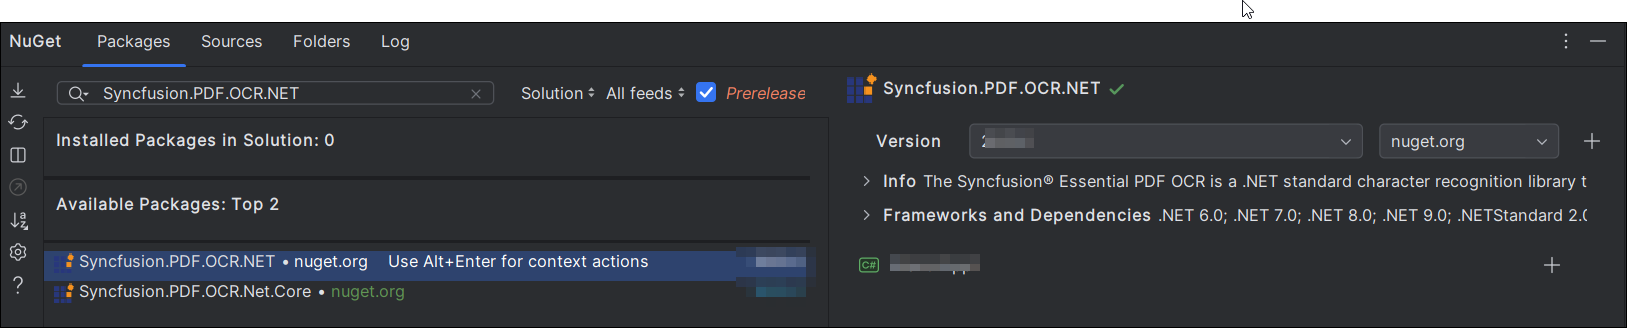
Step 2: Install the NuGet package from NuGet.org:
- Click the NuGet icon in the Rider toolbar and search for Syncfusion.PDF.OCR.Net.Core
- Ensure NuGet.org is selected as the package source
- Select the latest Syncfusion.PDF.OCR.Net.Core package from the list
- Click the + (Add) button to add the package
Step 3: Include the following namespaces in Program.cs:
using Syncfusion.OCRProcessor;
using Syncfusion.Pdf.Parsing;
Step 4: Include the following code sample in Program.cs using the PerformOCR method of the OCRProcessor class:
// Initialize the OCR processor
using (OCRProcessor processor = new OCRProcessor())
{
    // Load an existing PDF document
    PdfLoadedDocument document = new PdfLoadedDocument(Path.GetFullPath(@"Data/Input.pdf"));
    // Set the Tesseract version
    processor.Settings.TesseractVersion = TesseractVersion.Version5_0;
    // Set OCR language
    processor.Settings.Language = Languages.English;
    // Perform OCR on the document
    processor.PerformOCR(document);
    // Save the processed PDF to disk
    document.Save(Path.GetFullPath(@"Output/Output.pdf"));
    // Close the document
    document.Close(true);
}
Step 5: Build the project.
Click the Build button in the toolbar or press Ctrl+Shift+B to build the project.
Step 6: Run the project.
Click the Run button (green arrow) in the toolbar or press F5 to run the application.
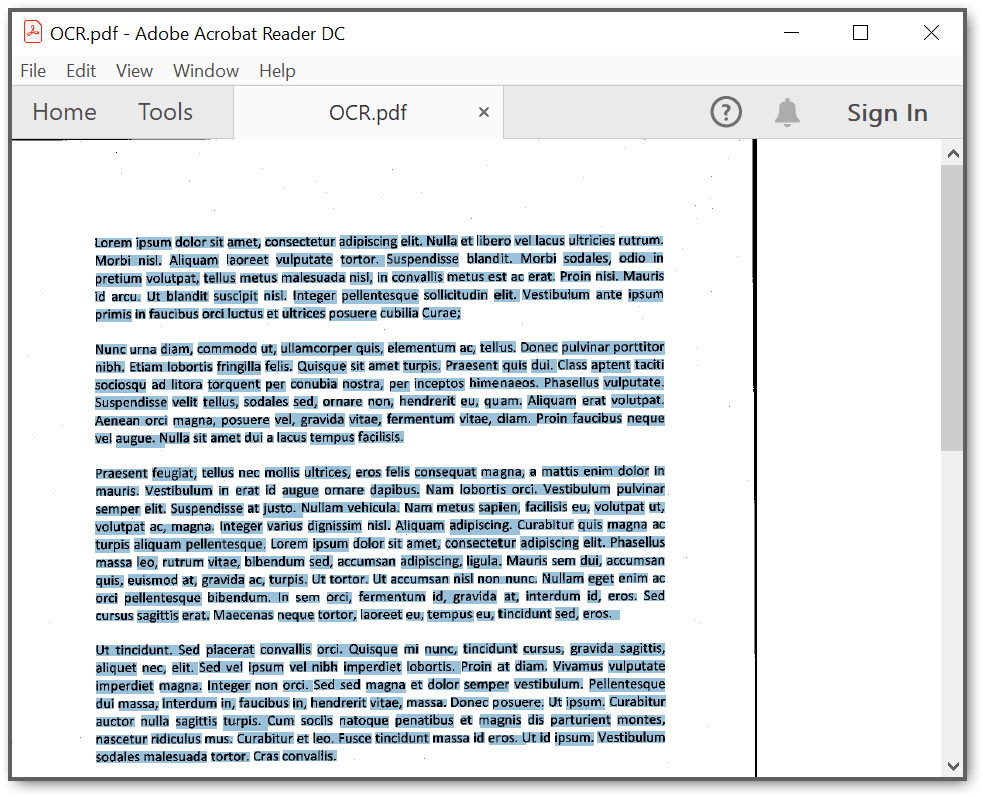
By executing the program, you will get a PDF document with extracted text as shown below:
A complete working sample can be downloaded from GitHub.
Click here to explore the rich set of Syncfusion® PDF library features.